pyramid2 v32 Results Charts
Four-layer adaptive evaluation on three held-out kitchen tasks (h3 / h4 / h5, HD-EPIC). Solver: Gemini 4. Examiner and judge: Gemini 3.1 Pro. The same h4 items were also replayed with Qwen3.5-35B-A3B. All runs on 2026-11-05.
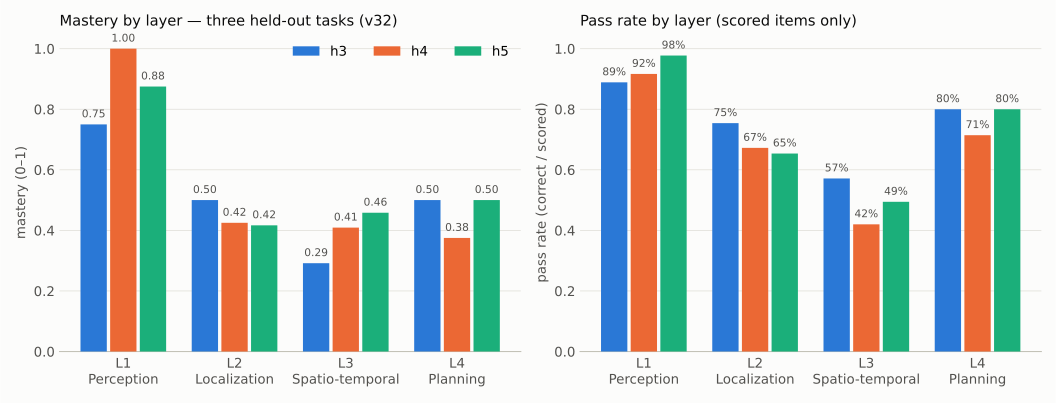
Mastery and pass rate by layer, per task
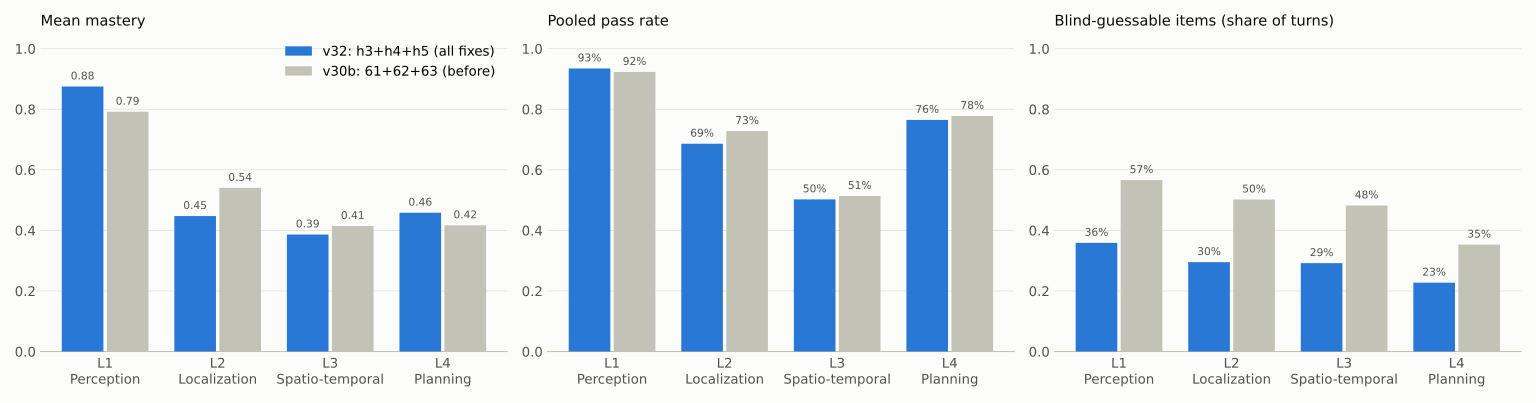
Before and after the fixes: v32 (h3+h4+h5) vs v30b (61+62+63)
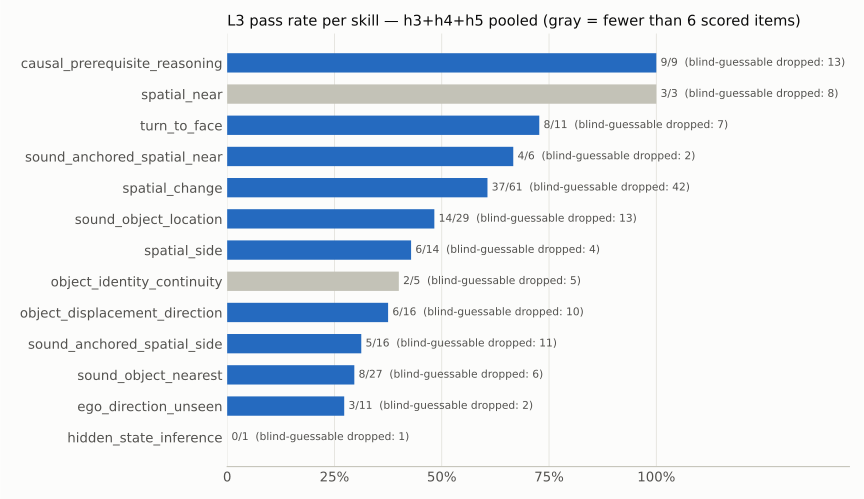
L3 pass rate per skill, three tasks pooled
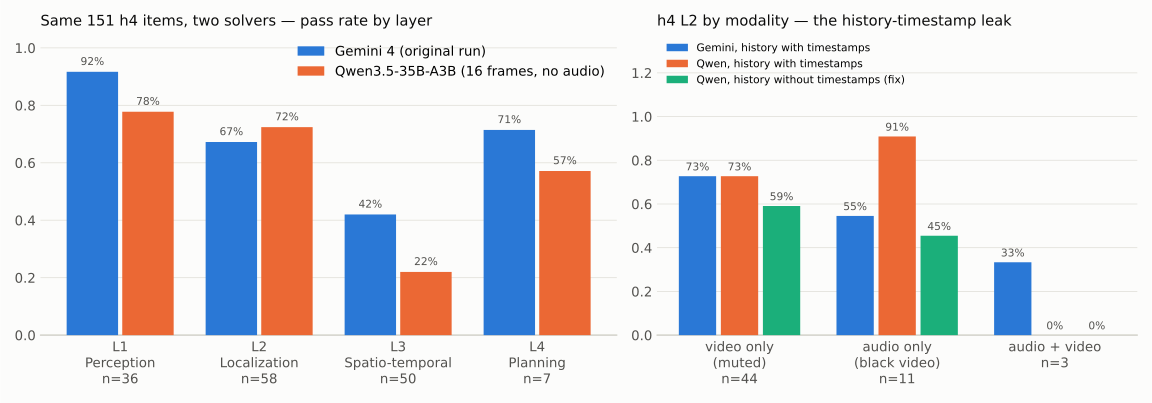
Same items, second solver: Gemini 4 vs Qwen3.5-35B-A3B (h4)
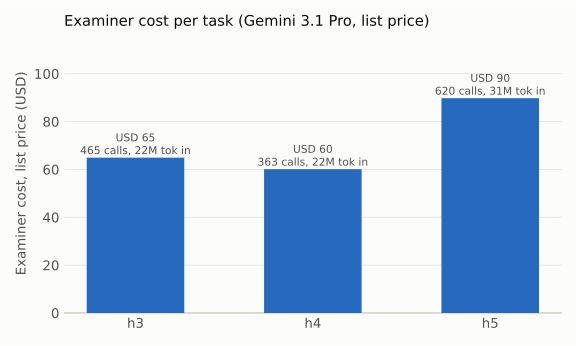
Examiner cost per task
Metrics by layer
| Layer | h3 mastery / pass | h4 | h5 | Pooled mastery / pass | Scored items | Blind-guessable share |
|---|---|---|---|---|---|---|
| L1 Frame Perception | 0.75 / 89% | 1.00 / 92% | 0.88 / 98% | 0.88 / 93% | 107 | 36% |
| L2 Localization × modality | 0.50 / 75% | 0.42 / 67% | 0.42 / 65% | 0.45 / 69% (leaked) | 223 | 30% |
| L3 Spatio-temporal Reasoning | 0.29 / 57% | 0.41 / 42% | 0.46 / 49% | 0.39 / 50% | 209 | 29% |
| L4 Planning (gap-filling) | 0.50 / 80% | 0.38 / 71% | 0.50 / 80% | 0.46 / 76% | 17 | 23% |
Three things to keep in mind when reading the charts: the L2 numbers include the history-timestamp leak; L4 single-choice items are easy on long tasks (distractors are steps about other ingredients, so the head segment alone identifies the answer); most L3 skills have only 1–16 scored items per task, so most staircase boundaries are estimates rather than converged values.